Stable Diffusion 3
Open text-to-image modelFree download text-to-image model
Highlights
What you can do with it
- Digital art creation from text prompts
- Image editing and concept work
- Game and film production assets
How to use it
- 1 Get the model from Stability AI's official page
- 2 Choose the parameter size that fits your hardware
- 3 Install it in a supported environment
- 4 Enter a text prompt and generate an image
- 5 Refine prompts for multi-subject scenes
Who it is for
Pros
- A free download is noted for the model
- Better spelling and multi-subject handling than earlier versions
- Several parameter sizes for different hardware
Limitations
- Licensing and deployment terms are set by the official site
- Large parameter versions need serious compute
- Prompt results vary and need iteration
What Stable Diffusion 3 is
Stable Diffusion 3 is a text-to-image model from Stability AI. It uses a diffusion transformer architecture with flow matching and comes in parameter sizes from 800M to 8B, with deployment options ranging from individual users to corporate clients. The release notes describe clear improvements over earlier versions in multi-character prompts, image quality and spelling accuracy, including correct output when prompts contain misspelled model names. Typical uses include digital art creation, image editing, and game and film production. The listing notes a free download; licensing and usage terms are set by the official site.
What you can do with it
- Generate high-quality images from text prompts
- Handle prompts with multiple subjects
- Get better spelling in rendered text
- Pick a parameter size that fits your hardware
Who it is for
- Digital artists creating illustrations and concept work
- Teams in game and film production
- Developers and studios deploying their own models
The release frames the model as a step toward safe, open and inclusive generative AI.
Smaller sizes are quicker to run but trade off some detail, so match the model to the job, and check the license page before any commercial release.
What to watch out for
The larger parameter versions need serious compute, so a personal GPU may only handle the smaller models. Licensing and deployment terms are set by the official site and should be checked before commercial use. Prompt results vary, and multi-subject scenes still need iteration to get the composition right. Because it is a downloadable model rather than a hosted service, updates and fixes arrive through new releases you install yourself, and running it well takes some learning.
FAQ
What is new in Stable Diffusion 3?
It improves multi-character prompts, image quality and spelling accuracy, and uses a diffusion transformer architecture with flow matching.
Which sizes are available?
Parameter sizes range from 800M to 8B, with deployment options from individual users to corporate clients.
Is it free?
The listing notes a free download. Licensing and usage terms are set by the official site.
Why it is free
What the official page says: free download
Free limits, trial length and features are decided by the official site and can change at any time.
Product preview
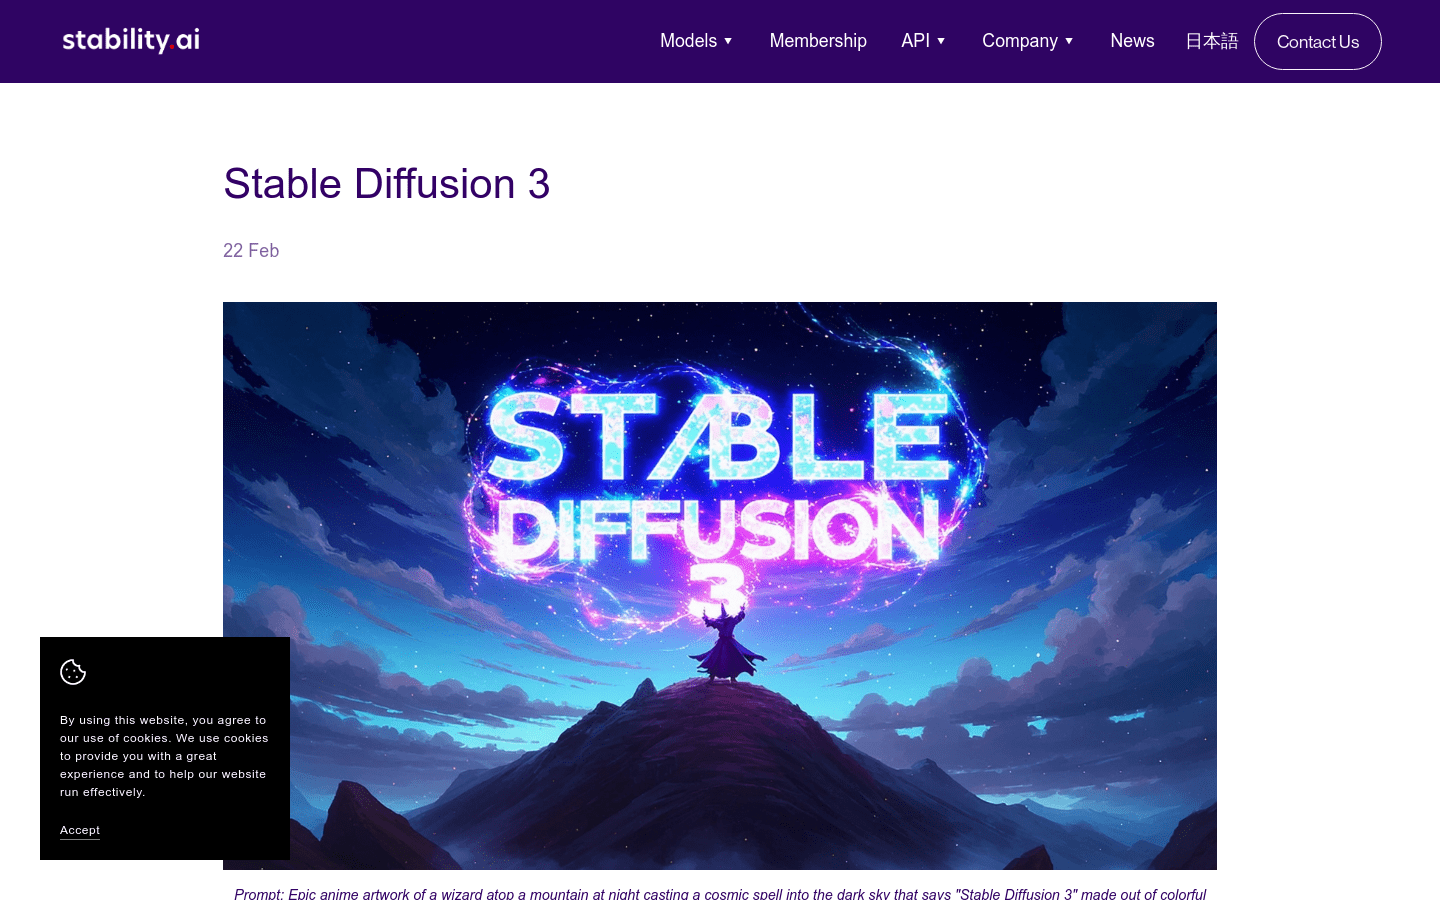
Screenshot archived from the listing page, for preview only.