WAVELINE EXTRACT
API for extracting data from PDFs, images, documentsDocument data extraction without training data
Highlights
What you can do with it
- Pull structured data out of PDF files
- Process images and spreadsheet files for data extraction
- Handle resume and passport processing workflows
- Automate data capture in file transfer scenarios
How to use it
- 1 Sign up and get access to the WAVELINE EXTRACT API
- 2 Send your document, image, or PDF to the API endpoint
- 3 Receive the extracted data in a structured response
- 4 Integrate the response into your application or workflow
Who it is for
Pros
- Works across documents, images, PDFs, and spreadsheets
- No training data needed to begin extracting
- A free STARTER plan allows testing before paid use
- Flexible plans from starter to enterprise scale
Limitations
- The free STARTER plan is limited, and pricing or limits can change
- As an API, it needs development work to integrate
- Extraction accuracy on complex layouts must be validated on your own files
- Handling personal documents like passports means following privacy rules and getting consent where required
What WAVELINE EXTRACT is
WAVELINE EXTRACT is a robust API built for extracting data from documents, images, and PDFs. It uses AI to pull data out of any supported document format without the need for training data, which removes one of the usual hurdles in document processing projects. The API handles multiple formats, including PDFs, images, and spreadsheet files, and the vendor says it adapts to a wide range of scenarios such as file transfers, resume handling, and passport processing. Pricing comes in three plans: a free STARTER plan, the POPULAR PRO plan, and an ENTERPRISE plan, so you can start small and scale later. Key selling points include full data extraction from PDFs, support for various formats, flexible pricing, and local solutions.
What you can do with it
- Extract data from PDFs, images, and spreadsheet files
- Run extraction without preparing training data
- Automate resume, passport, and file transfer processing
- Start on the free STARTER plan and move to paid tiers as you grow
Who it is for
- Developers who need document extraction inside an application
- Teams that process resumes, passports, or transfer documents
- Businesses that handle large volumes of PDFs and images
- Projects that want a plan that scales from starter to enterprise
What to watch out for
The free STARTER plan is a starting point, not a permanent free tier, and plan limits and pricing can change, so check the API documentation before you build on it. As an API rather than a click-and-go app, WAVELINE EXTRACT requires development work to integrate, so factor in engineering time. Extraction results on complex or unusual layouts should be validated against your own documents before you rely on them in production. If you process personal documents such as passports or resumes, you are responsible for handling that data lawfully and with the consent of the people involved.
FAQ
What is WAVELINE EXTRACT?
It is a robust API that extracts data from documents, images, and PDFs using AI, without requiring training data.
Is there a free plan?
Yes, WAVELINE EXTRACT offers a free STARTER plan, along with POPULAR PRO and ENTERPRISE plans.
What files does it support?
It supports multiple formats, including PDFs, images, and spreadsheet files.
Why it is free
What the official page says: 免费
Free limits, trial length and features are decided by the official site and can change at any time.
Product preview
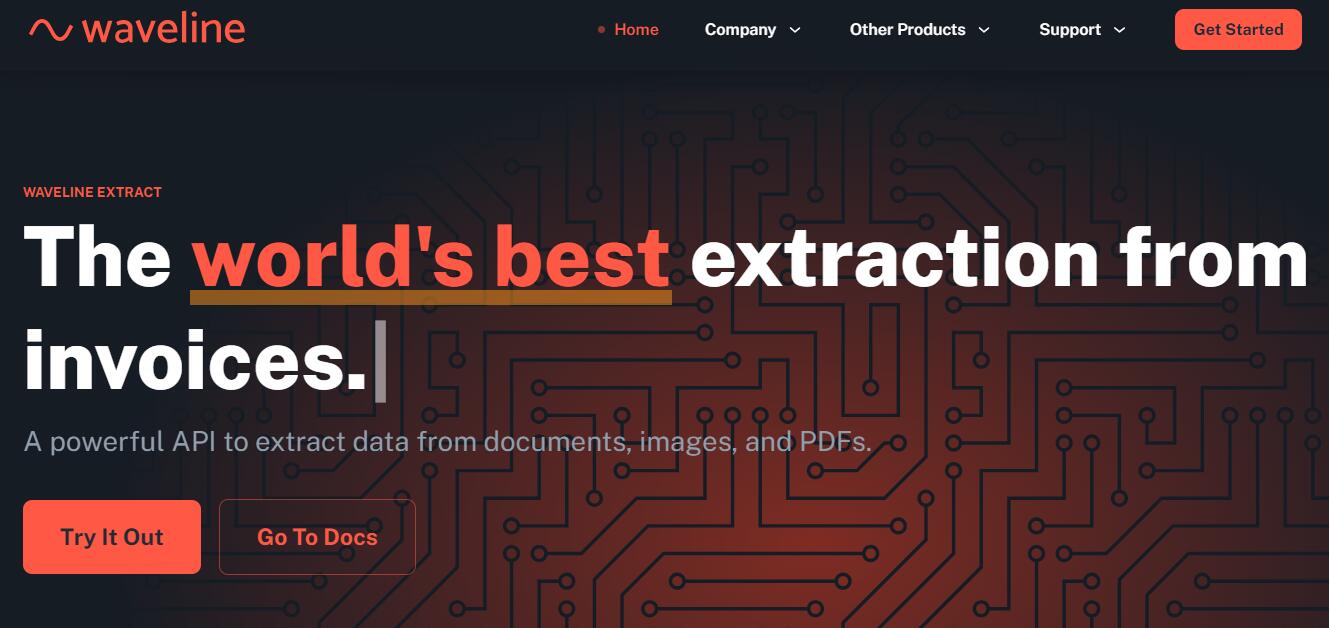
Screenshot archived from the listing page, for preview only.