
Spark Robin
Gemini based visual response modelA visual AI partner for multimodal work
Highlights
What you can do with it
- Sending images and text together for a richer answer
- Working through complex visual material with context
- Speeding up interactive creative workflows for a team
How to use it
- 1 Open Spark Robin and check the current access options
- 2 Send an image together with your text prompt
- 3 Review the visual output and refine your request
- 4 Use it alongside your team's creative workflow
Who it is for
Pros
- Strong focus on visual and multimodal responses
- Reads context inside an image, not just the prompt
- Aimed at fast, interactive creative work
Limitations
- Payment model is unclear, so free access is not confirmed
- A 50 percent off discount is shown but exact pricing is missing
- Specialized for visual tasks, less suited to plain text jobs
What Spark Robin is
Spark Robin is an AI model built on Gemini that focuses on rich visual responses and multimodal interaction. Its main job is to help you read and work with complex visual information, understanding the context inside an image rather than only reacting to a short text prompt. The page describes it as working like a visual AI partner, giving enhanced visual output for teams that need fast, interactive creative workflows and multimodal results. On pricing, the page is not fully clear: it shows a 50 percent off discount but does not state an exact payment model, so it may be a paid product with a discount or one that also offers a trial. Treat any free access as unconfirmed until you check the site directly.
What you can do with it
- Send images and text together for multimodal interaction
- Get richer, more context aware visual output from a request
- Use it as a visual partner when working through complex visual material
- Support fast interactive creative workflows inside a team
Who it is for
- Teams that need quick multimodal visual output
- Creators working with image heavy material and complex visual context
- Anyone who wants a Gemini based assistant tuned for visual responses
What to watch out for
The pricing details are vague. The page shows a discount but does not confirm whether there is a lasting free tier or only a limited trial, so do not assume free access will continue. Because the exact payment model is not stated, verify costs on the official site before you rely on it for ongoing work. It is also a specialized model aimed at visual tasks, so it may not replace a general assistant for pure text jobs, and any free or discounted offer could change without notice. Output quality will still depend on the images and prompts you provide.
FAQ
Is Spark Robin free?
The page shows a discount but does not confirm a lasting free tier, so treat free access as unconfirmed until you check the site.
What is it based on?
It is an AI model built on Gemini, focused on rich visual responses and multimodal interaction.
Who is it for?
Teams and creators who need fast, multimodal visual output and help processing complex visual information.
Why it is free
What the official page says: 免费试用免费
Free limits, trial length and features are decided by the official site and can change at any time.
Product preview
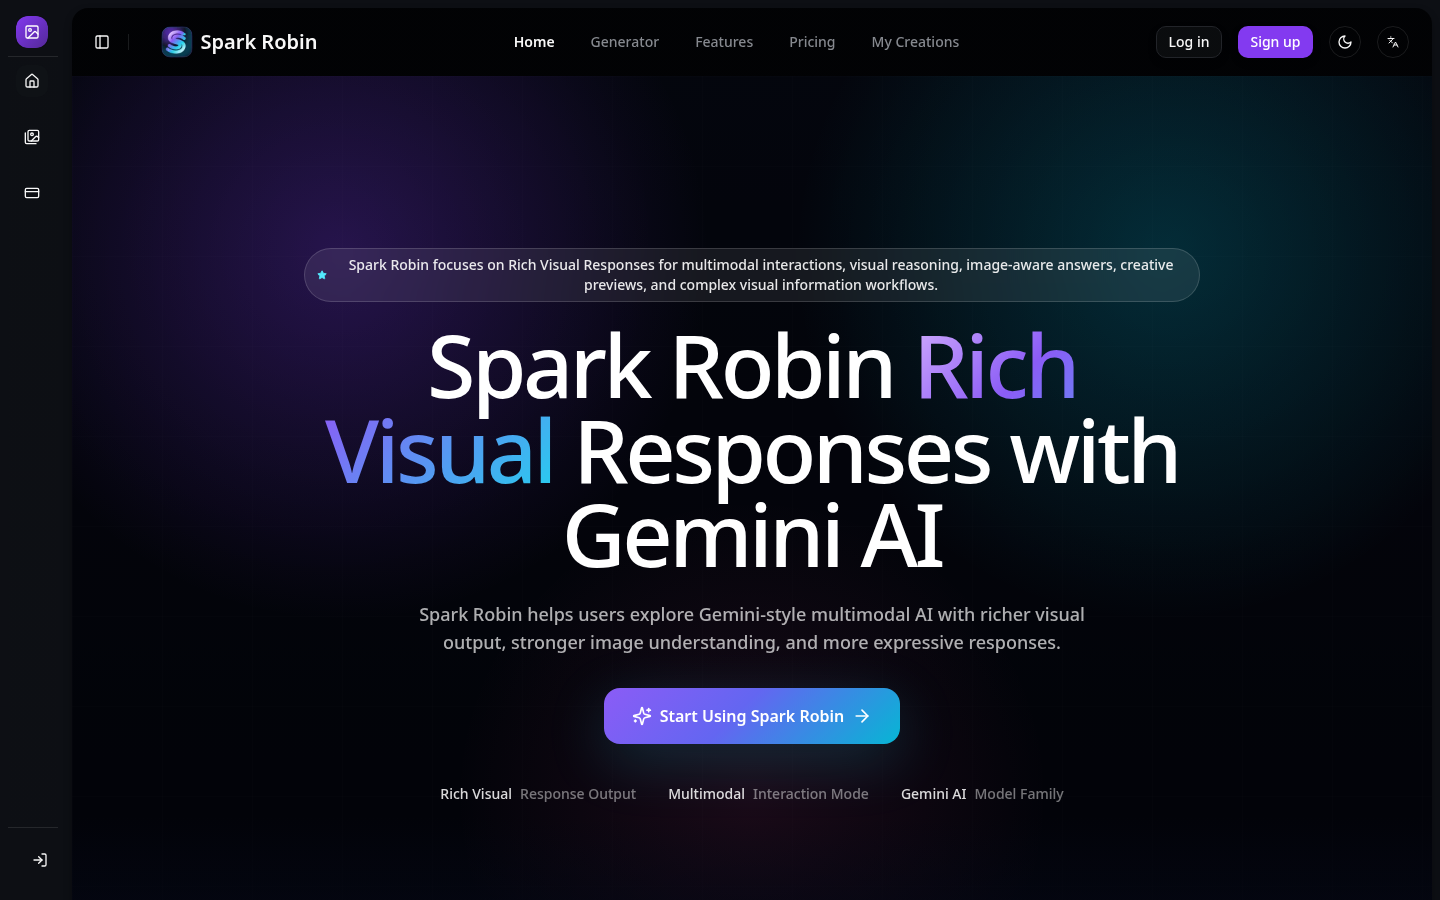
Screenshot archived from the listing page, for preview only.